Supermicro urges buyers to judge AI factories by deployment readiness
Supermicro says data pipelines, storage and validation should be planned with GPUs, but it offered no comparable time-to-online data.
By Colin Brandt · Enterprise Reporter
· 3 min read
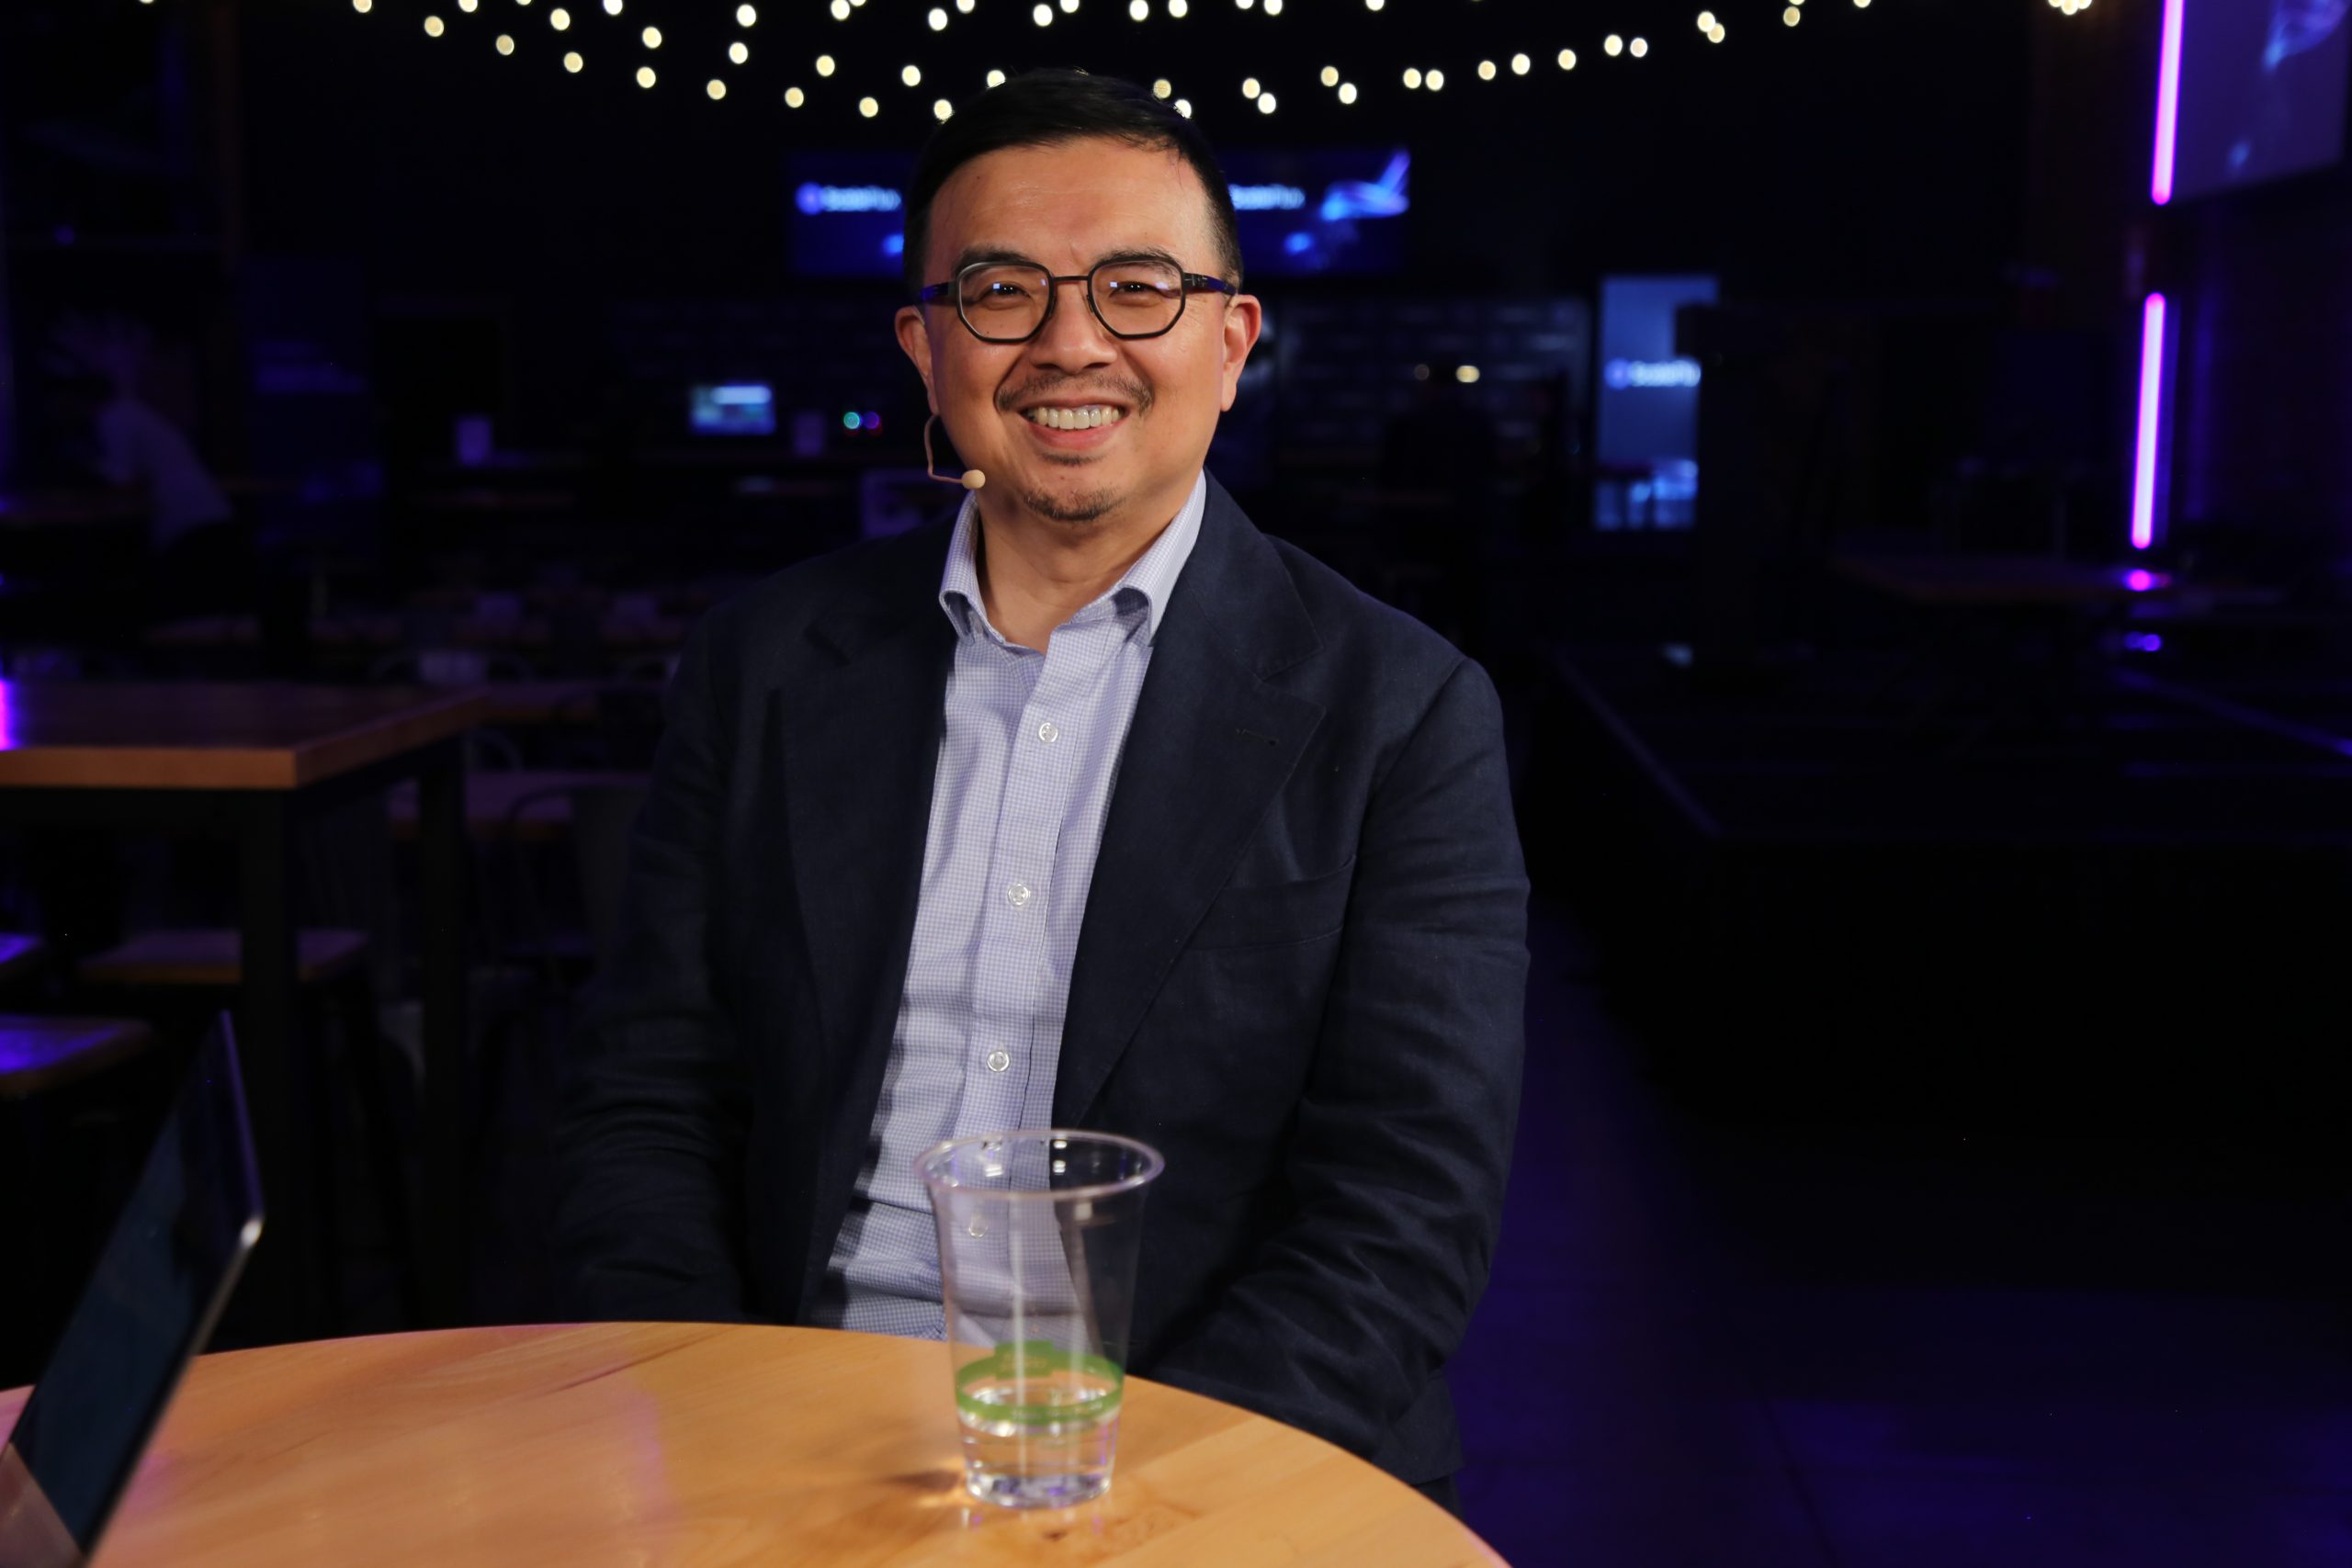
Supermicro AI factory deployment should be judged by whether a complete system can be put into production, not by GPU count alone, Ben Lee, the company’s director of solution management, said at the AI Data Pipeline Forum 2026. The position shifts attention from acquiring accelerators to integrating the storage, networking and validation work that can keep installed compute from becoming usable capacity.
Lee did not argue that GPU sizing is unimportant. He said customers still need to size clusters for their workloads, but should design the data pipeline and storage alongside the compute build. In the October interview with theCUBE, he described differing pipeline needs for data such as video, PDFs and articles.
For buyers, GPU count measures installed compute capacity. Supermicro’s proposed measure is operational readiness: whether compute, data and the rest of the system have been configured and validated well enough to enter production. The supplied evidence contains no standard metric, methodology, customer count or deployment-cost or schedule results for comparing those measures.
What can delay an AI factory after GPUs arrive?
Lee said some customers confront data-pipeline and storage questions only after building their GPU clusters. He also said rising SSD and memory prices had made storage sizing harder in 2026. Supermicro’s answer is to plan storage with compute, including through partners such as VAST Data, rather than treating it as a subsequent procurement problem.
The company is also selling itself as a single accountable provider for what Lee called one large computer. In its product materials, Supermicro describes systems that combine GPU compute, storage, networking, power delivery, cooling, software and management, with validation running from components through systems, racks and clusters. Those are Supermicro’s descriptions of its offering, not independently measured deployment outcomes.
That bundle overlaps with cloud infrastructure’s core compute, storage, networking and management layers, while Supermicro is pitching an integrated, AI-specific deployment package. Its materials say reference architectures, rack-level testing and deployment services can speed time to online and reduce deployment risk. The evidence provided does not establish whether those claims hold against other suppliers or against customer-built systems.
Lee said small configuration failures can become larger issues at cluster scale, citing the need for validation at each level. He also said Supermicro planned a cluster-level management tool for the fourth quarter of 2026, though the supplied material does not say that the product launched.
Supermicro has used the same deployment framing in customer marketing. In an August 2025 announcement about Lambda’s infrastructure expansion, Supermicro characterized the rollout as occurring in “record time.” The announcement did not provide a time measurement, a baseline or a comparator, so it does not verify the claim.
The practical distinction is narrow but useful: capacity tells a buyer how much accelerator hardware has been installed; production readiness asks whether the full system is ready to serve its intended workload. The current evidence supports Supermicro’s case for considering both. It does not show how buyers should rank GPU capacity, time to production, cost or availability when those measures conflict.
This story draws on original reporting from SiliconANGLE.